Model Routing: A Technical Overview of the State of the Art
Routing & Technology

Maximilian Keller
Founder, Kontinent

Model routing dynamically decides which model and how much compute handles a request, with the goal of staying on the Pareto frontier of cost, quality, and latency. This post is an overview of the field: the approaches, the state of research, how much can realistically be saved, the common router architectures, and the known limitations and failure modes. It is not a building manual, but rather a map of the territory.
Key Takeaways
Routing selects one model per request to balance cost, quality, and latency; the basic forms are pre-generation and cascade.
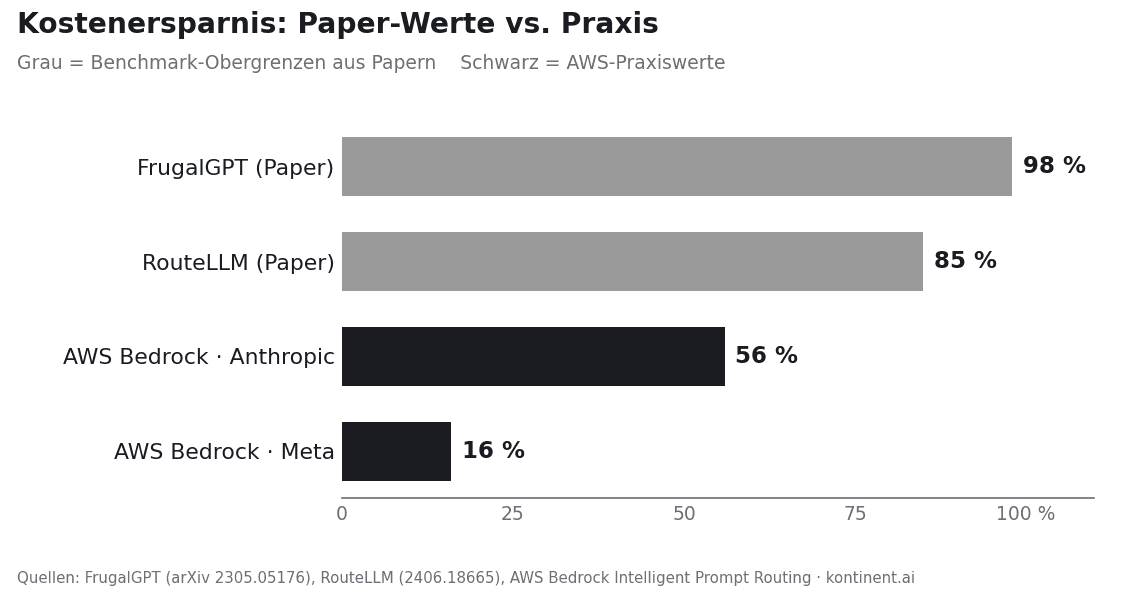
Paper figures of 85% to 98% are upper bounds; AWS's 16% to 56% per model family is more realistic.
According to RouterArena, real routers remain significantly below the Oracle; typical failure modes include Routing Collapse and Confounder Gadget attacks.
The primary benefit remains cost savings, complemented by reliability, observability, and, for EU products, compliance.
The conceptual "why"—namely, choosing the cheapest model that still solves the task—is covered in the foundational post on price-performance routing. This text contextualizes how advanced the technology behind it currently is.
What Routing Is, and What It Is Not
A router is a function that assigns a request from a pool of models to exactly one, in order to maximize expected quality under a cost budget or minimize costs under a quality floor. The threshold at which the choice falls to the stronger model encodes the trade-off between cost and quality. In literature, this is called "willingness-to-pay."
The fundamental distinction relates to the timing of the decision.
Pre-generation (predictive) | Post-generation (Cascade) | |
|---|---|---|
Decision | before generation, solely from the query | after a real response |
Cost / Latency | one decision, cheap | multiple calls, higher latency |
Robustness | estimates difficulty blindly | sees the actual response |
Examples | RouteLLM, Hybrid LLM, Arch-Router | FrugalGPT, AutoMix |
Neighboring techniques should be distinguished from this. Mixture of Experts routes tokens within a single model. Ensembling and Fusion query multiple models and combine the responses, trading higher cost for higher quality. Speculative Decoding accelerates a single model using a draft model. Model routing, on the other hand, selects exactly one model in order to save costs.
The State of Research
The field is surprisingly mature. FrugalGPT (Stanford, 2023) established cascades, Hybrid LLM (Microsoft, ICLR 2024) introduced the encoder-based difficulty router, and RouteLLM (Berkeley, ICLR 2025) introduced routers trained on preference data along with metrics like APGR (Average Performance Gap Recovered) and CPT (Call-Performance Threshold). Evaluation is conducted using RouterBench (using the AIQ metric, with zero-router and Oracle-router baselines) and, most honestly, RouterArena (ICLR 2026). Its core finding is sobering: all real routers remain significantly below the Oracle, primarily because they struggle to detect when a small model is already sufficient.
How Much Routing Saves
Research cites spectacular figures: FrugalGPT up to 98% cost savings with cascades, RouteLLM over 85% on MT-Bench at 95% of GPT-4 quality. These values apply to the respective benchmarks and are upper bounds under favorable difficulty distributions, not expected production values. Closer to reality are the averages published by AWS itself for Bedrock Intelligent Prompt Routing: depending on the model family, 16% to 56% savings while maintaining top quality.
Whether routing pays off depends on three conditions: heterogeneous difficulty of requests, a wide price gap between usable models, and high volume. If one of these is missing, for example, because nearly all requests are difficult, almost everything ends up in the top tier anyway. With a price gap of less than about factor 3 to 5, or if over 70% to 80% of requests go to the most expensive tier, the effect remains minimal.
The Three Basic Strategies
Practically all routers can be traced back to three basic patterns, which are often combined in production.
Rule-based Tiering deterministically assigns requests to a tier based on signals like task type, query length, or required capabilities. This approach is transparent and requires no ML, but it is rigid and assumes that the task type is known beforehand. According to RouterArena, good tiering alone captures a large portion of the achievable savings.
Classifier Routing estimates complexity beforehand using a small, fast model. In research, the encoder-classifier (BERT, DeBERTa, ModernBERT) dominates, with a forward-pass in the millisecond range; RouteLLM found the tiny Matrix Factorization to be the most cost-effective. The known weakness: routers overfit to their training distribution and fall to random-guess levels out-of-domain unless training data is augmented.
Cascade Routing operates post-generation. First, the cheap model responds, then its confidence is evaluated, and the request is escalated to a stronger model only in case of uncertainty. This is more robust because a real response is available, but it incurs additional latency and multiple calls. Confidence-based deferral is often, but not always, optimal according to research (Jitkrittum et al., NeurIPS 2023).
Router Architectures and Latency
The choice of router architecture is itself a cost-latency trade-off, because the overhead of making the decision must not eat up the savings. In practice, usable routers lie in the range of 10 to 50 ms.
Architecture | Latency | Character |
|---|---|---|
Matrix Factorization | tiny, sub-ms | most cost-effective baseline (RouteLLM) |
Encoder-Classifier (ModernBERT) | few ms | the standard workhorse |
Embedding + kNN | embedding call + lookup | simple, good for clustering |
Small-LM-Router (~1.5B) | tens to hundreds of ms | most flexible, but most expensive decision |
Routing is Primarily a Constraint Problem
Before cost even becomes a factor, hard capabilities restrict the pool: context window, tool calling, JSON schema support, multimodality, streaming, and, for an EU product, the processing region. A model lacking a required capability is not a valid choice, regardless of price. For large model pools, routing is therefore first a constrained optimization over the permissible sub-pool, and only then a question of cost. Data residency counts as one of the hard constraints: a failover that silently sends a request to a non-EU region turns a service outage into a compliance violation.
The Prompt Cache Economy
The most frequently underestimated effect is not an ML question, but an accounting one. If a subsequent request switches providers, that provider's prompt cache prefix is lost, and the nominally cheaper model can become more expensive net-net. Additionally, tokenizers differ: the same prompt has a different token count depending on the model, and therefore a different price. The real cost of a route is thus composed of input and output tokens, cache read and write adjustments, as well as expected retry or cascade costs. This is the origin of the common rule of thumb, "if you route, pin": session pinning keeps the cache warm as soon as more than one model is in play.
Semantic Caching
Semantic caching stores responses based on embedding similarity of the query rather than exact matches. A hit short-circuits the routing completely because no model call is required. The trade-off is the potential for false-positive hits if the similarity threshold is set too loosely. For FAQ-style workloads with many repetitions, it is the single largest savings lever.
Failure Modes
Routing Collapse. As the cost budget increases, many routers systematically tilt toward the most expensive model, even when a cheap one would suffice. The paper "When Routing Collapses" (2026) describes this and attributes it to an objective-decision mismatch: routers predict scalar scores but make discrete comparative decisions, and small errors flip the ranking order. As a countermeasure, it proposes EquiRouter, a decision-aware, ranking-based approach.
Confounder Gadgets. "Rerouting LLM Routers" (COLM 2025) demonstrates query-independent token sequences that, when prepended to any request, reliably force the router to choose the expensive model. Such a denial-of-wallet attack does not degrade response quality and bypasses perplexity filters. Protection methods include input screening and cost anomaly detection per user.
The GPT-5 Lesson. The most public lesson was delivered by OpenAI itself. At the launch of GPT-5, the auto-router failed, causing difficult requests to land in the cheap model, making the system appear "dumber"; simultaneously, a silent safety router redirected certain prompts without documentation. The case has since served as proof that non-transparent, silent re-routing poses a trust risk.
How Routing is Evaluated
Robust comparisons are run against four baselines: random routing, the Oracle as an upper bound, the best single model, and an equal-cost single model. Common metrics are cost at iso-quality, quality at iso-cost, as well as APGR, CPT, or AIQ. In production, shadow deployments (the router runs in parallel without serving its choice), canary testing on a small slice of traffic, and offline replay from logs are added. RouterArena shows that real routers consistently underperform compared to the Oracle here, primarily because they too rarely recognize when a small model is sufficient.
Two Trends Reshaping Routing
Two developments are changing the landscape without erasing the core utility. Falling frontier prices are slightly narrowing the price gap, and providers are increasingly building routing in-house: GPT-5's internal router, Gemini's thinking budgets, and the reasoning_effort parameter already decide how much compute a request receives before an external router ever sees it.
Nevertheless, the most tangible reason for routing remains cost savings. As long as tasks vary in difficulty and the price gap is wide, using the cheapest suitable model saves real money, in practice often in the range of 60 to 80 percent. A gateway makes this lever practical and adds reliability through failover, observability, and, for EU products, compliance. Cost savings and control come from the same layer; they are not mutually exclusive.
Where an EU Gateway like kontinent.ai Fits In
For an EU product, both come together: the cost savings from routing and the control over it. A gateway that bundles OpenAI, Claude, Gemini, Mistral, and other models behind an OpenAI-compatible endpoint sends every request to the cheapest suitable model and turns switching models into a string replacement instead of an integration project. If processing is EU-hosted, data residency across the entire pool becomes a hard constraint instead of a task per provider, including EU-only failover. That is where kontinent.ai fits in: as an EU-hosted access point to 167 models in 240 provider variants, combining real cost savings with compliance, reliability, and observability, rather than playing them off against each other.
Frequently Asked Questions
Pre-generation or Cascade: what is the difference?
Pre-generation (predictive) decides before generating based solely on the query, which is cheap and low-latency, but blind to actual difficulty. Cascade decides after a real response and is more robust, but costs additional latency and multiple calls. In practice, both are combined.
How much does routing realistically save?
Not the 85% to 98% cited in papers—those are benchmark upper bounds. More realistic are AWS's own averages of 16% to 56% per model family, and even then, only with heterogeneous difficulty, a wide price gap, and high volume.
What is Routing Collapse?
The phenomenon where routers, as the budget grows, send everything to the most expensive model even though cheap ones would suffice. The cause is predicting scalar scores for what are actually discrete decisions.
Why can a cheaper model be more expensive net-net?
Because when switching providers, the prompt cache prefix is lost. A warm cache is often worth more than the lower list price, which is why the rule of thumb "if you route, pin" has established itself.
Is external routing still relevant in light of falling prices?
Yes. The biggest lever remains cost savings: as long as requests vary in difficulty, the cheapest suitable model saves real money. Falling prices and provider-internal routing only diminish the effect at the margins. Additionally, reliability, observability, and, for EU products, compliance are provided from the same layer.
As of: August 2026 · kontinent.ai. Research figures (FrugalGPT, RouteLLM, RouterArena, AWS Bedrock, etc.) are benchmark or manufacturer specifications and do not represent guaranteed production values.
